Multimodal Humor Detection in Videos via Domain-Specific Representations and Deep Hybrid Fusion Networks
Soft Computing (Springer Nature), 2026
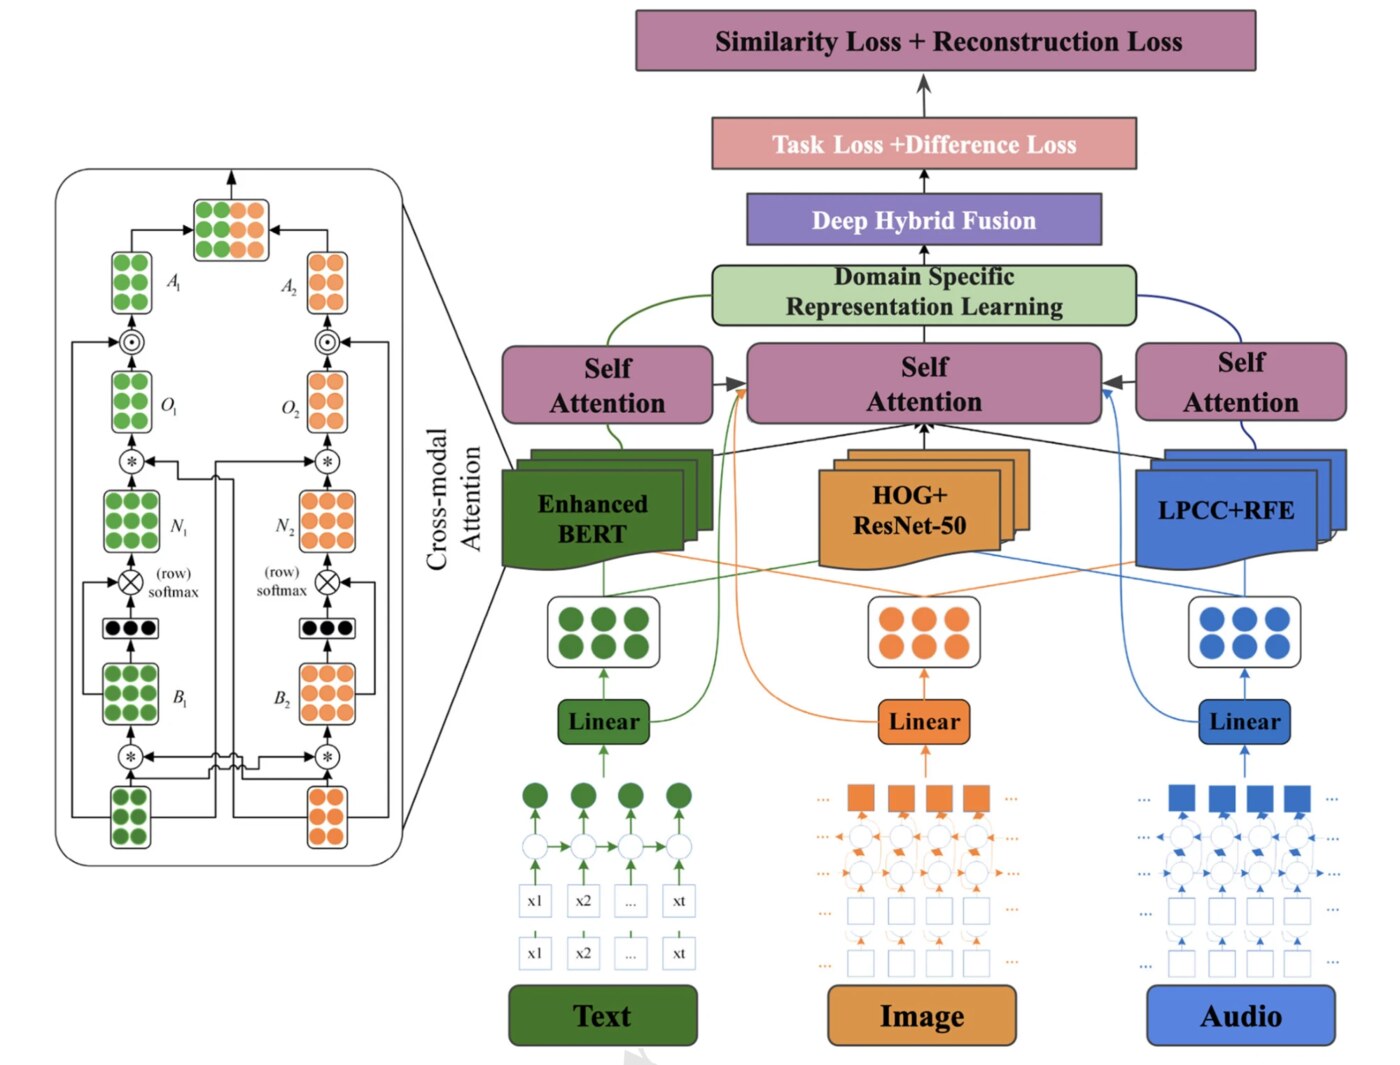
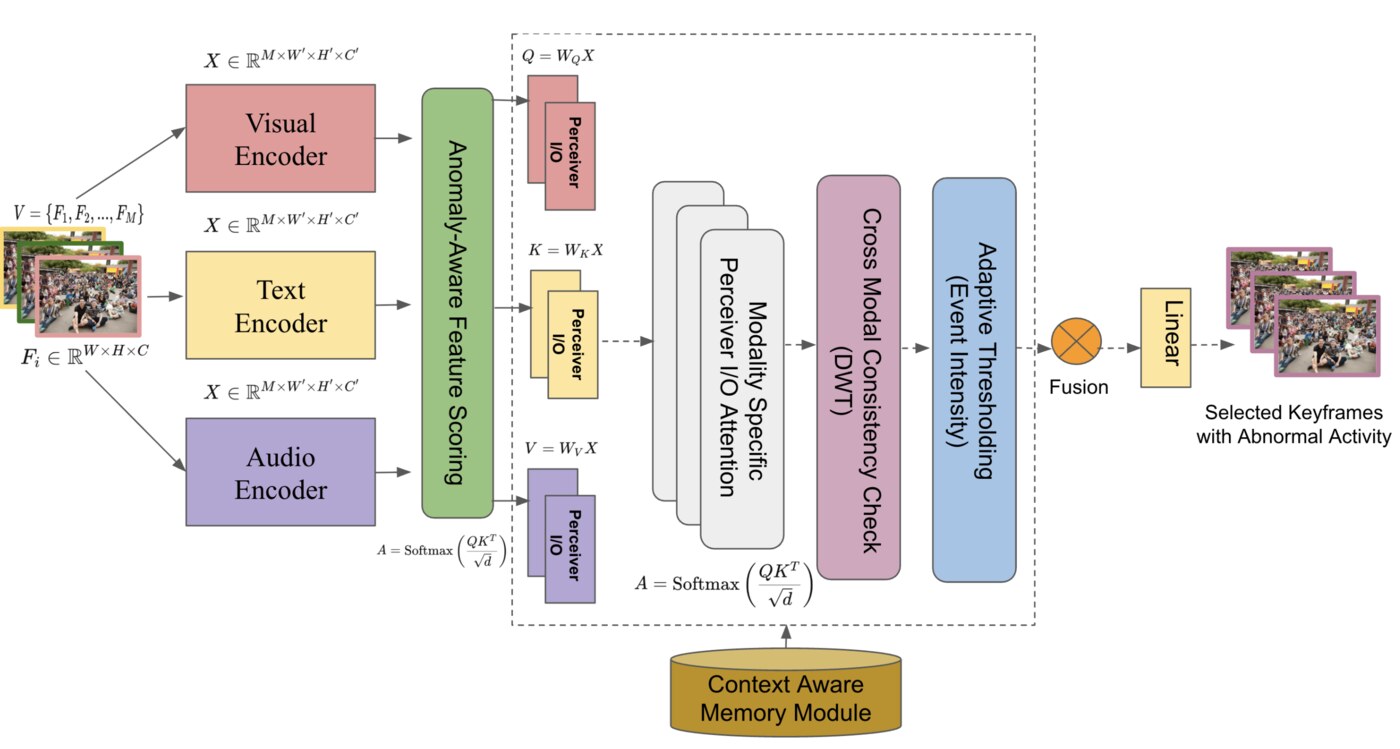
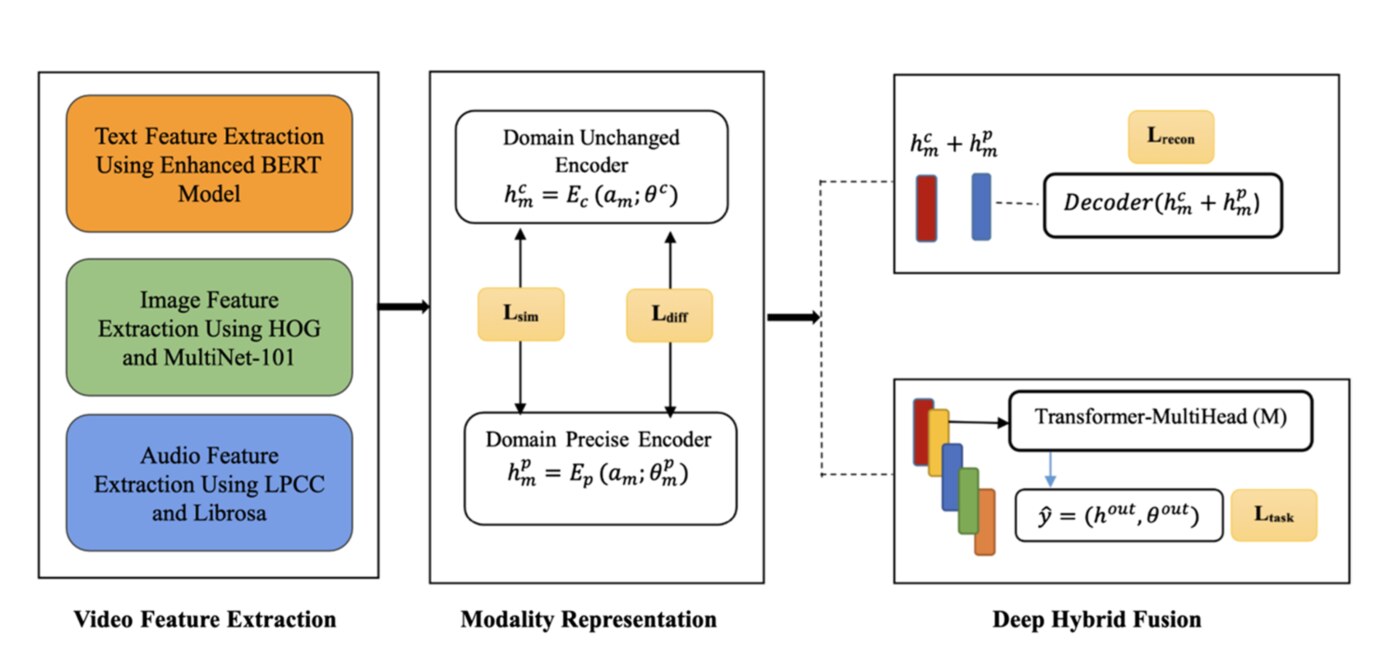
Humor in videos is hard to detect because cues are spread across text, visuals, and audio that are misaligned in time, imbalanced, and noisy. This framework combines Domain-Specific Representation Learning, which separates modality-invariant and modality-specific features with a Bi-LSTM, and a Deep Hybrid Fusion network that merges them through cross-modal attention with suppression, reaching up to 95.8% accuracy on IEMOCAP, CMU-MOSI, and CMU-MOSEI.