CAMMEL-ViT: Context-Aware Memory with Lightweight Vision Transformers for Medical Image Segmentation
MIUA 2026 — Medical Image Understanding and Analysis, University College Dublin, 2026
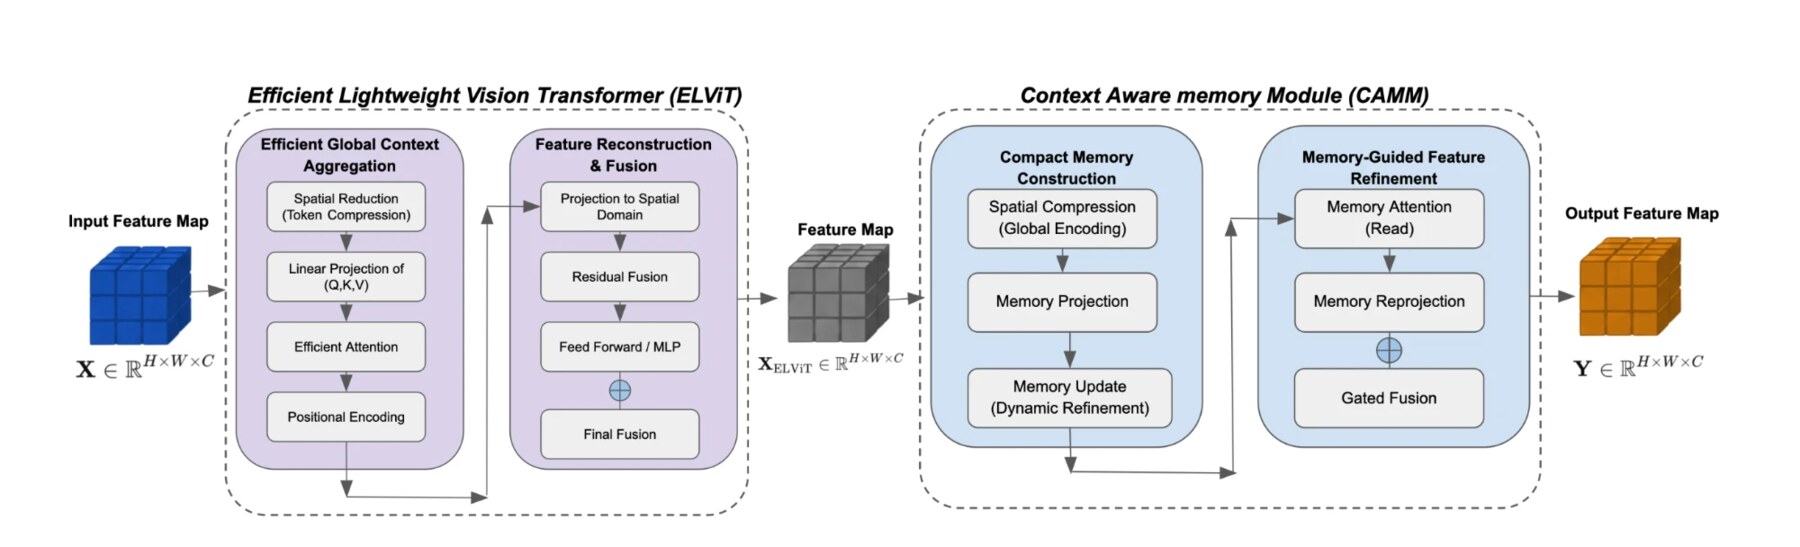
Medical image segmentation requires precise anatomical boundaries, long-range context, and efficient computation across both slice-wise and volumetric settings. CAMMEL-ViT is a dimension-agnostic CNN–Transformer encoder–decoder for 2D and 3D medical image segmentation; the same design applies to 2D slices and 3D volumetric patches by swapping convolution, pooling, normalization, and upsampling for their dimensional counterparts.
The architecture separates three roles:
- Multi-scale convolutional encoding for local structural detail.
- Efficient Lightweight Vision Transformer (EL-ViT), which compresses tokens spatially and models global dependencies at reduced resolution, avoiding the cost of dense full-resolution attention.
- Context-Aware Memory Module (CAMM), which builds a compact global memory and injects it into bottleneck features through memory attention and gated residual fusion. Unlike attention-only fusion, this memory prior improves anatomical coherence and reduces fragmented predictions.
Experiments on BraTS, ACDC, and BTCV show improved Dice and HD95 over representative CNN, transformer, and hybrid baselines with favorable computational cost.
Accepted in July 2026 and presented at the Medical Image Understanding and Analysis conference (MIUA 2026), University College Dublin, Ireland. Developed at the Centre for Imaging Technologies, Ramaiah Institute of Technology.